Flash-Next + RTX 4080 spill: Spark vs EVO-X3 quality×cost
Flash-Next 3-stage race with RTX 4080 Vulkan spill on EVO. Spark wall_sum 1083s vs EVO+4080 5321s. EVO wins arch3d first-pass; angry fails 12/12 on EVO.
Bottom line. Does Flash-Next run on EVO-X3 with an RTX 4080 layer spill, and how does Playwright render_ok quality compare to DGX Spark? It runs. wall_sum: Spark 1083s vs EVO+4080 5321s (~5×). EVO fails angry 12/12.
Stacks: Spark = NVFP4 · SGLang · :30000. EVO = ROCmFP4 GGUF · llama.cpp Vulkan1+Vulkan0 · -ts 56,8 · -c 32768 · :8080. Same protocol as the quality×cost race (arch3d → angry → snake, dynamic N).
Totals
| Spark | EVO + RTX 4080 | |
|---|---|---|
| arch3d → first pass | 357s (r2) | 267s (r1) |
| angry → first pass | 628s (r3) | 12/12 fail (cap) |
| snake → first pass | 98s (r1) | 367s (r2) |
| stages passed | 3/3 | 2/3 |
| wall_sum | 1083s (~18 min) | 5321s (~89 min) |
| decode (pass rounds) | ~37 tok/s | ~21–26 tok/s |
4080 spill proves load + inference. Under the quality gate, Spark is far cheaper. EVO’s bottleneck is not only speed — angry HTML never clears the gate.
Setup · 4080 spill
| DGX Spark | EVO-X3 + 4080 | |
|---|---|---|
| GPU | GB10 UMA ~128GB | 8060S + RTX 4080 (Vulkan1,Vulkan0) |
| weights | Flash-Next NVFP4 | Flash-Next ROCmFP4-FAST ple16 GGUF (~88G) |
| serve | SGLang | -sm layer -ts 56,8 -c 32768 --jinja |
| note | — | With -c 4096, outputs truncate ~3.8k and fail closed_html. Need 32k for arch3d pass. |
Stage 1 · arch3d
EVO passes on r1 (267s) — shorter wall than Spark’s first pass (357s / r2). Once context is long enough to close the document, 3D HTML clears the gate on both boxes.
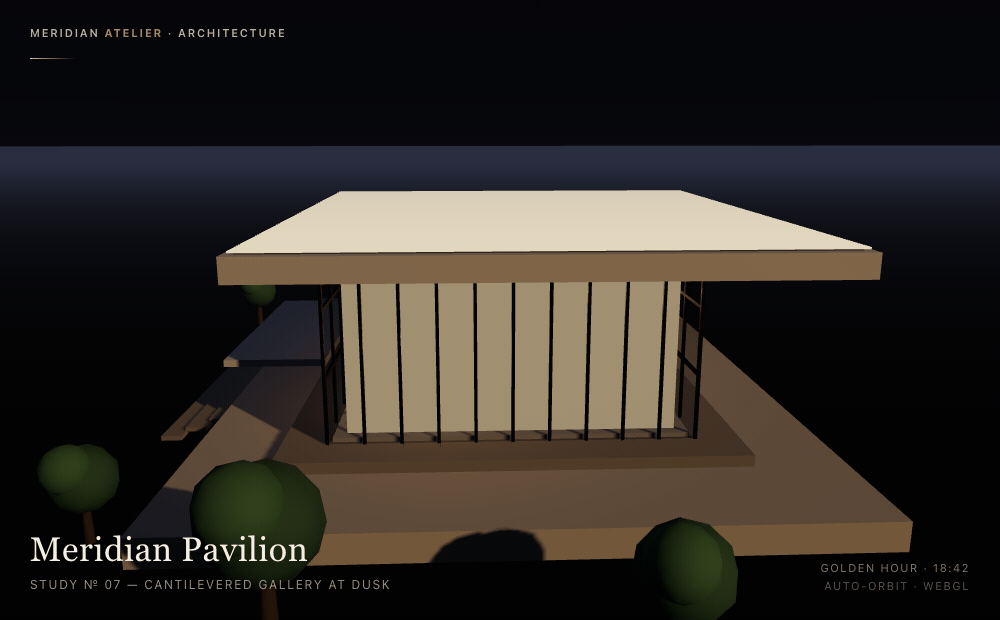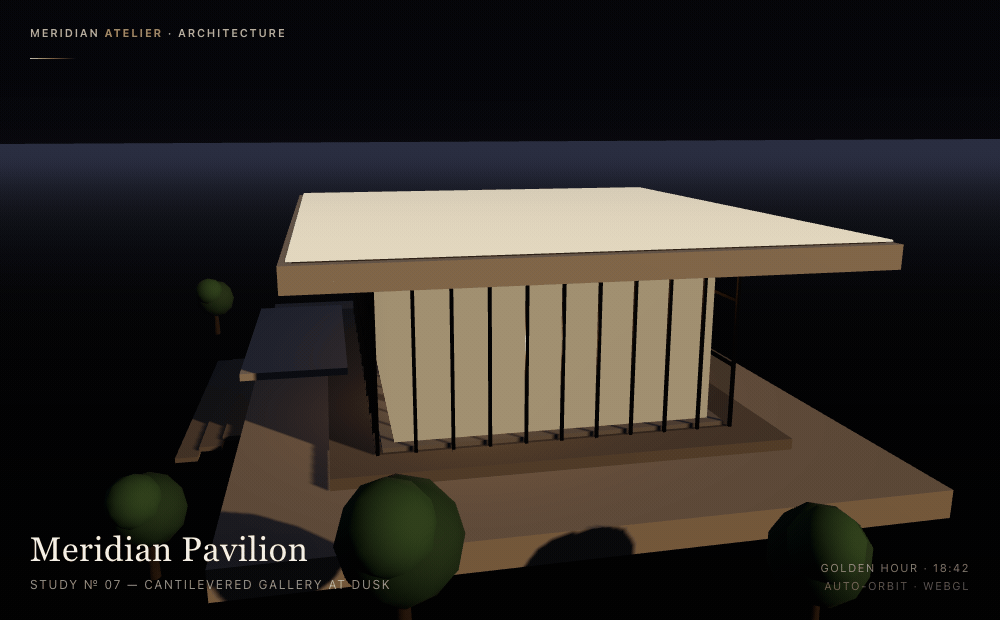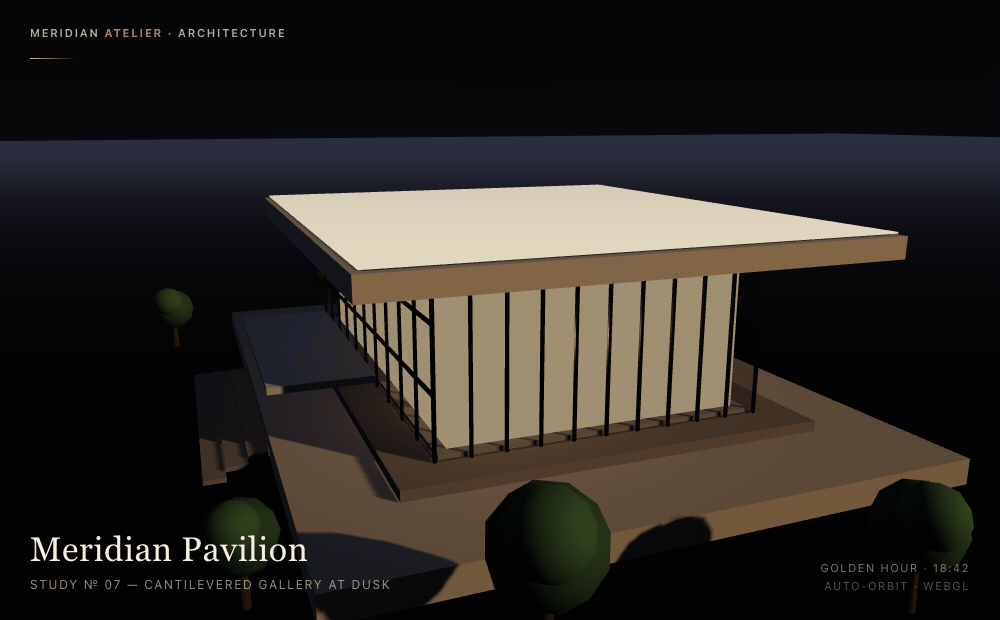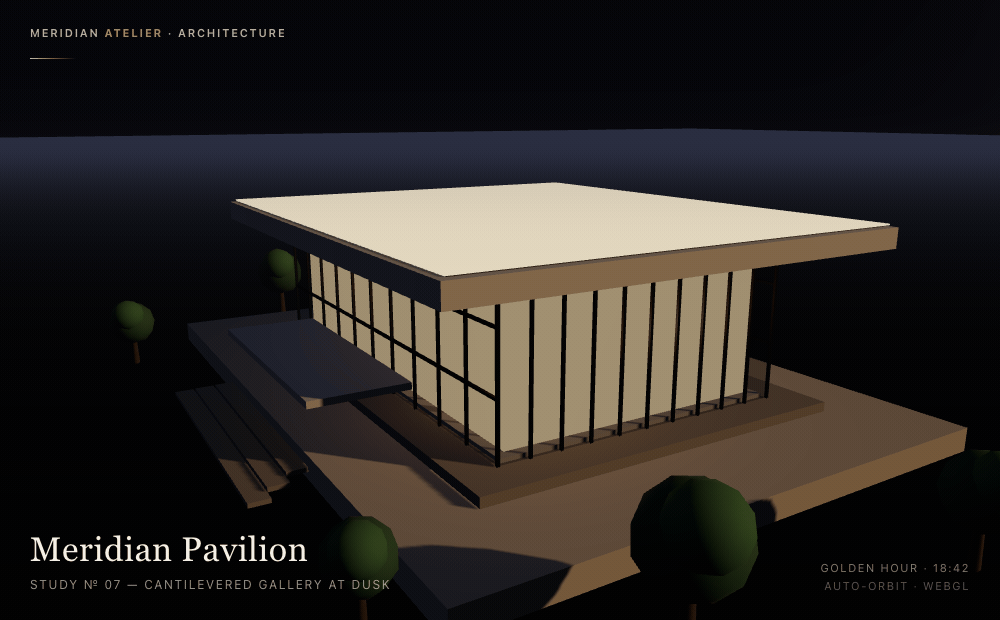
37.3 tok/s · 122s · 4559 tok
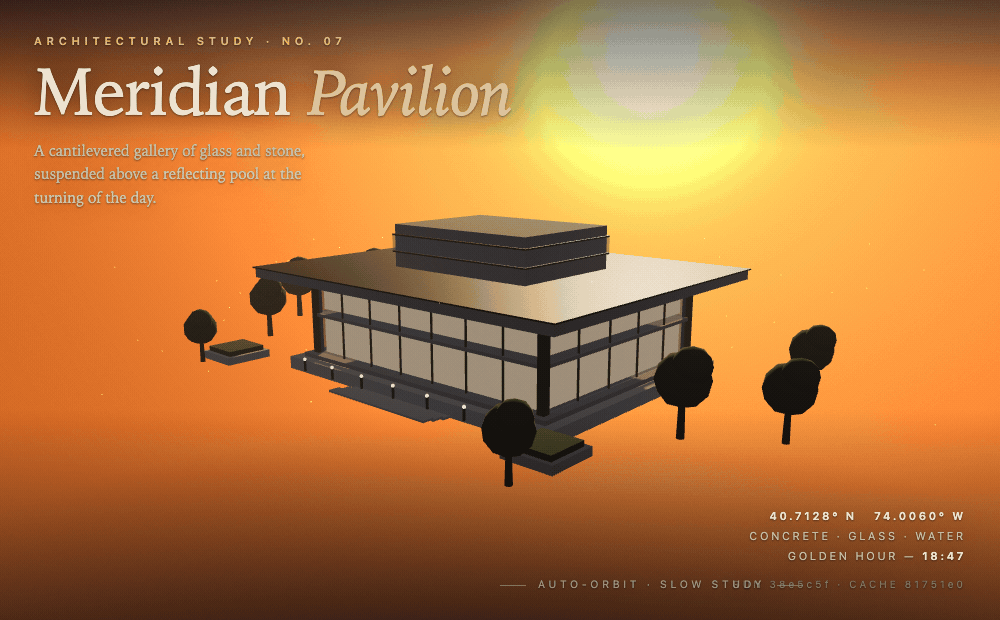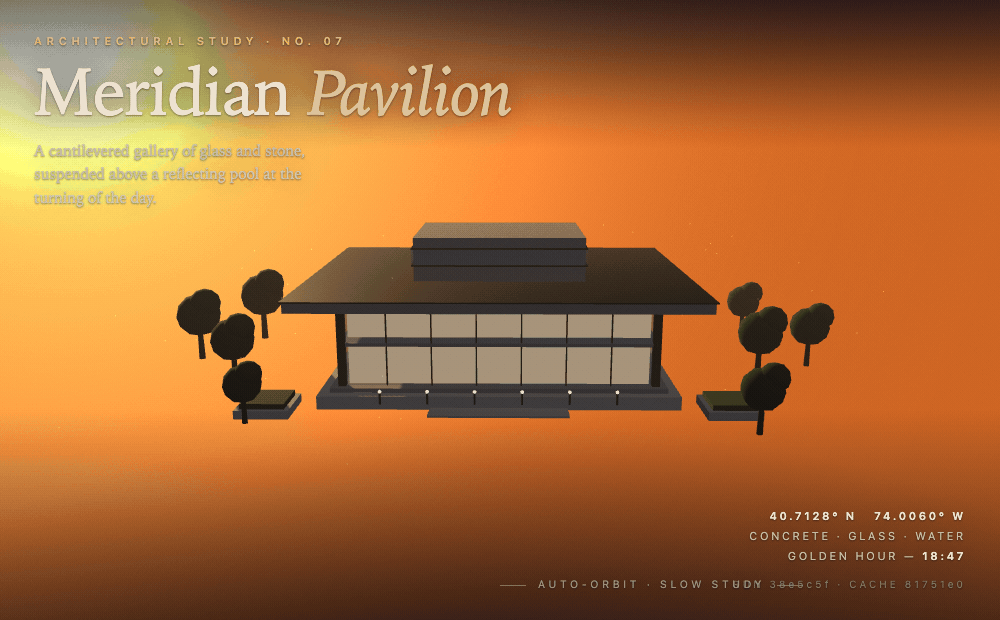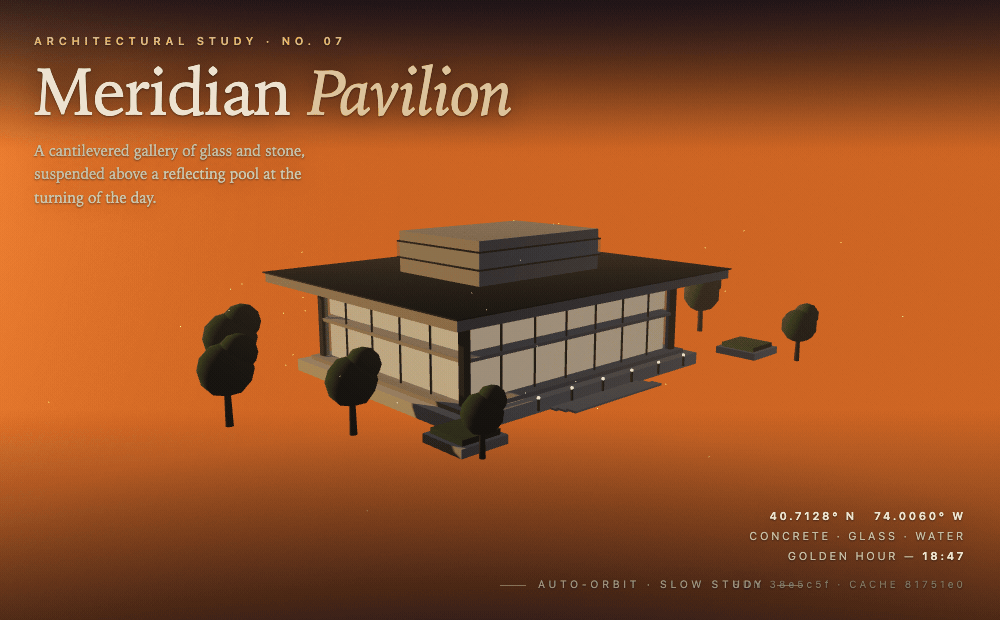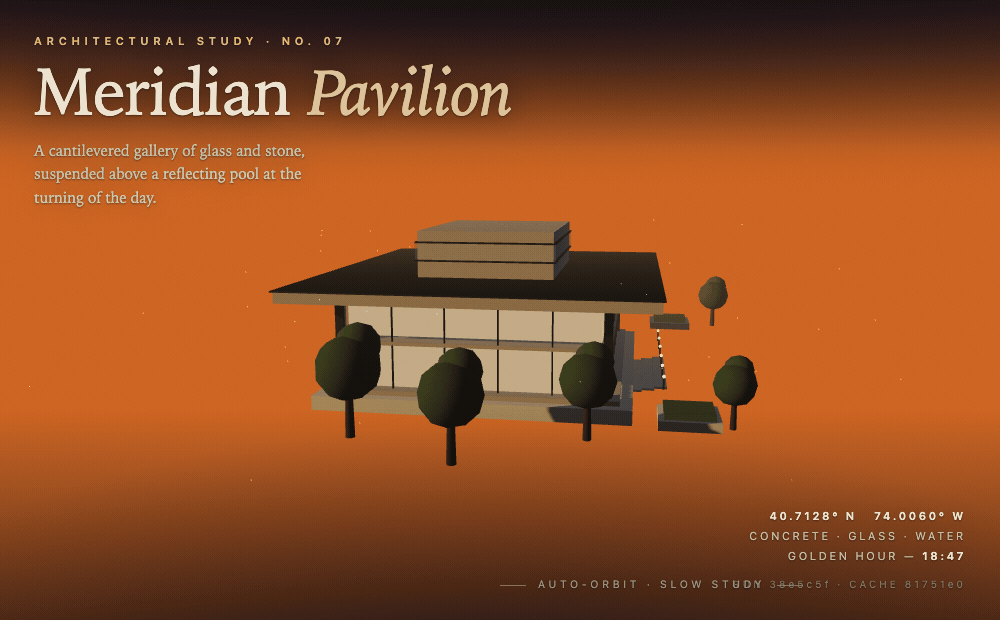
25.6 tok/s · 267s · closed_html OK
Stage 2 · angry
Spark passes at r3 (628s). EVO+4080: 12/12 render_ok=false — often missing requestAnimationFrame / input hooks. Burning 8k tokens still does not yield a playable slingshot. Worse than the prior AMD-only Flash race (angry eventually passed).
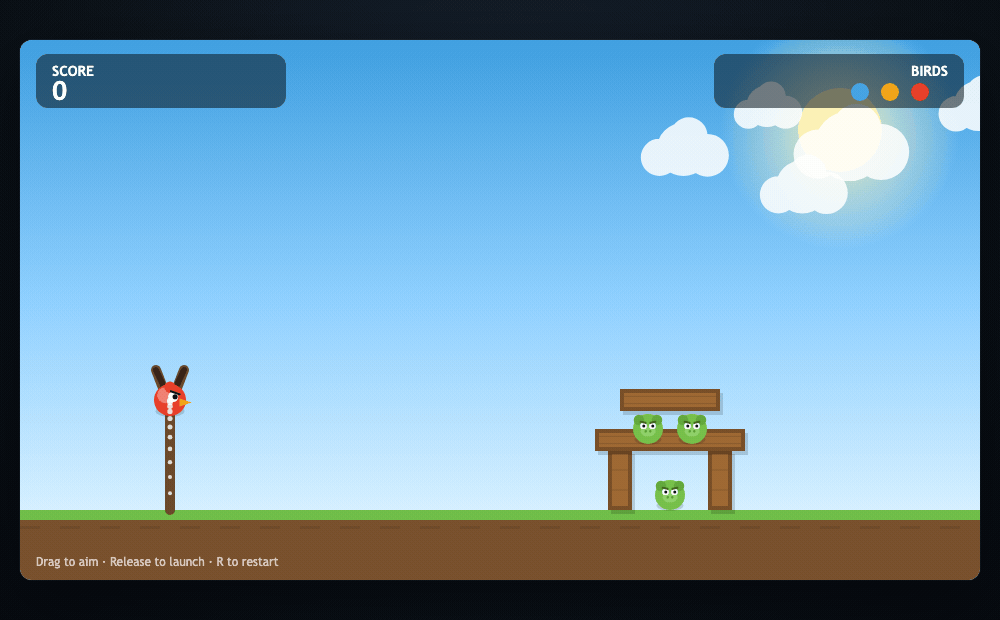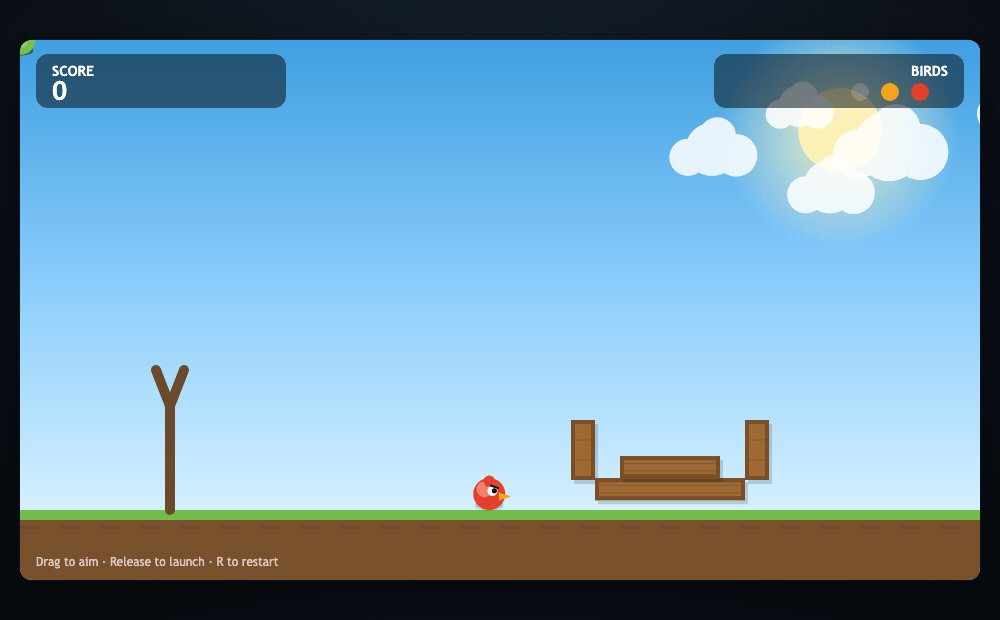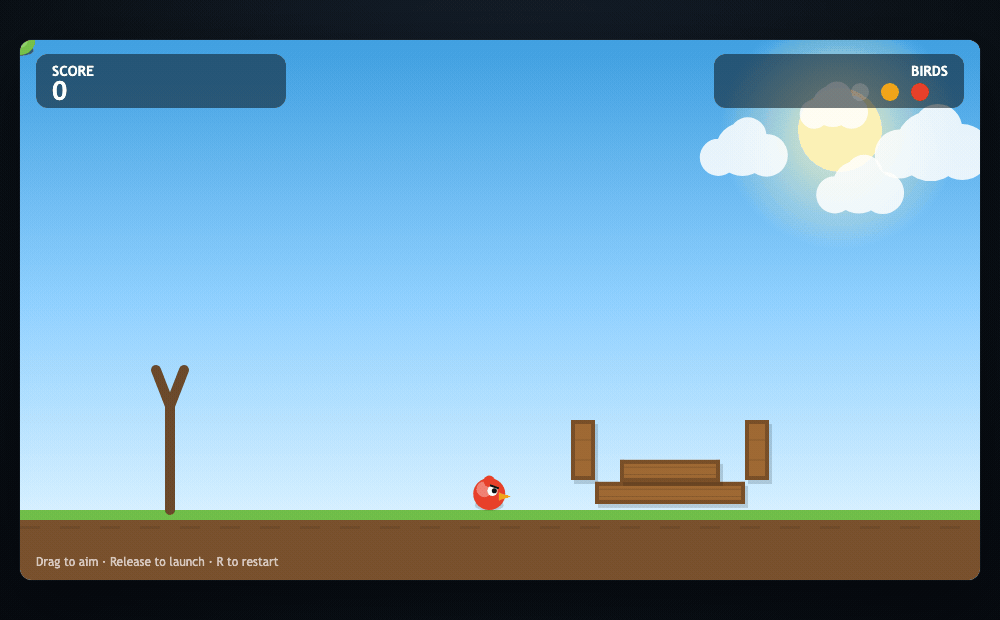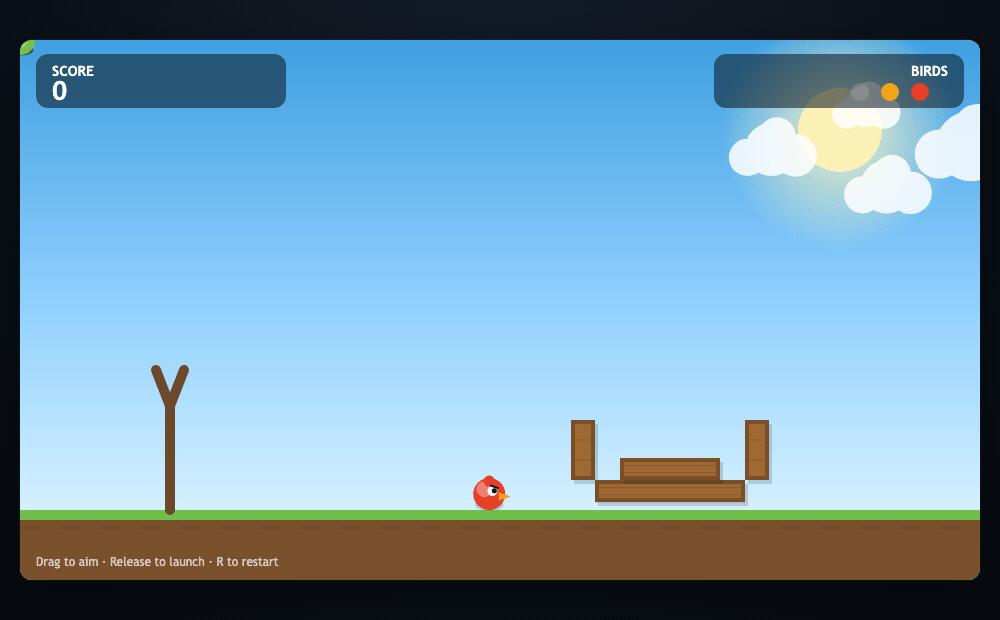
Stage 3 · snake
Both pass. Spark r1 (98s · 37 tok/s), EVO r2 (367s · 20 tok/s).
How to read this
- 4080 spill works for serving ~88G Flash-Next via AMD+NVIDIA layer split. Keep
-clarge. - Quality ≠ speed: EVO decode ~70% of Spark; most of the wall_sum gap is angry retries.
- Prior AMD-only Flash (wall_sum 3374s, angry eventually passed) is not a clean A/B — this post is only the same gate after adding the 4080.
Source: pipeline-flashnext-spark-vs-4080-v2/pipeline-20260903T151241Z.json · makespan 5403s.